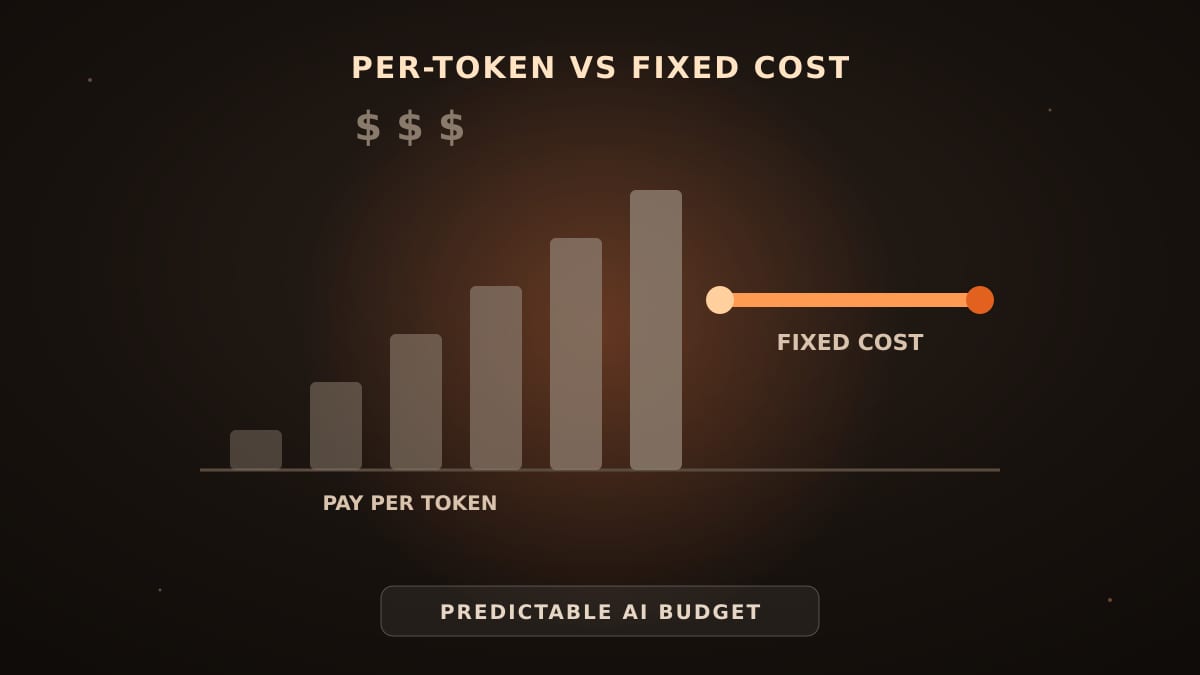
Quick summary: Cloud AI APIs bill per token — roughly per word fragment — for both what you send and what the model writes back. Document Q&A, long conversations and AI agents multiply token usage, so costs rise with adoption. A Local AI with a fixed cost per plan breaks that link.
What a token is
A token is a small piece of text, often part of a word. Providers count input tokens (your question plus everything you attach or retrieve) and output tokens (the answer), and price them per million. Output tokens are usually more expensive than input tokens.
Why bills grow faster than expected
Document Q&A sends large chunks of your documents with every question, so a one-line question can cost thousands of input tokens. Chat history is resent on every turn, so long conversations get more expensive as they continue. AI agents plan, call tools and check their own work in loops, which can consume many times the tokens of a single answer. And success itself is a cost driver: the more employees adopt the tool, the higher the bill, with no natural ceiling.
The hidden costs
Beyond the per-token price there are seat licences, premium model tiers, rate limits that force upgrades, and the engineering time spent monitoring and capping usage. Many finance teams end up restricting usage just to keep the budget predictable — which defeats the purpose.
How fixed-cost Local AI changes the maths
With Local AI, the model runs on hardware you own or rent at a fixed price. Once it is running, a thousand questions cost the same as ten. That makes it easy to encourage usage across the company, run document-heavy workloads and experiment with automation without watching a meter. The trade-off is an upfront decision about hardware sized to your needs.
Where DABO AI fits
DABO AI does not charge per token or per request. Each plan has a fixed cost, and the Free plan is free with no time limit for up to 5 users and 100 documents. You run it on your own GPU machine — an NVIDIA card with 16 GB VRAM or more, or a Mac with Apple Silicon — and choose a model from DABO-Lite to DABO-Ultra that is just big enough for the job, so you do not overpay for hardware. For repetitive paperwork, teams can cut manual handling time by up to 90%, depending on the workflow.
A simple way to compare
Estimate how many questions or documents your team will process per month in a year, not today. Multiply by an average token count including attachments and history, then by the provider's rates. Compare that 3-year total with the cost of a Local AI setup. For steady, document-heavy use, the fixed-cost option usually wins well before the end of the period.
Frequently asked questions
Why is document Q&A so token-hungry on cloud AI? Because the relevant passages are sent with every question as input tokens.
Is Local AI always cheaper? Not for very light, occasional use. It becomes cheaper as usage grows and stays predictable.
Does DABO publish prices? The Free plan is free. Pro, Max and Ultra are quoted by scale — contact info@dabotech.ai.